Devanagari Handwritten Character Dataset
Overview
Devanagari Handwritten Character Dataset is a grayscale image classification dataset with 46 classes and 32 x 32 images. The official split is preserved:
Train: 78,200 images.
Test: 13,800 images.
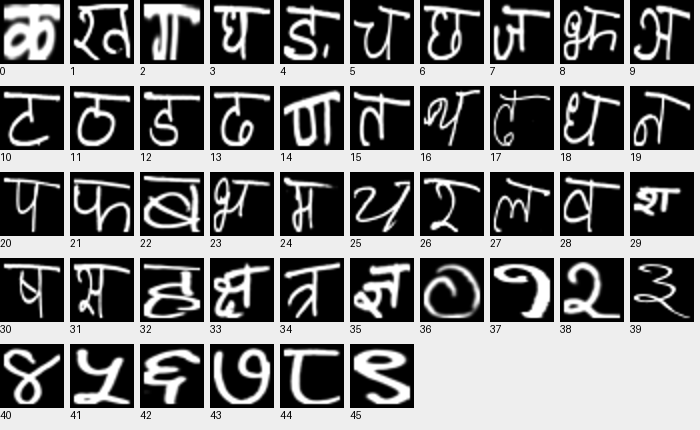
Data Structure
Each sample contains image (a grayscale PIL.Image.Image) and
label (an integer class ID).
Labels 0-35 follow the numeric archive folders character_1_ka through
character_36_gya. Labels 36-45 correspond to digit_0 through
digit_9. The original folder names are available in
ds.features["label"].names. This mapping uses numeric character order,
not lexicographic folder order.
The original two-pixel padding is retained. Both splits use the same ZIP archive, which is downloaded once. Images are stored as their original PNG bytes; neither resizing nor RGB conversion is applied.
Usage
from stable_datasets.images import Devanagari

ds = Devanagari(split="train")
sample = ds[0]
print(sample["image"].size, sample["label"])

# Load both official splits.
splits = Devanagari()
print(len(splits["train"]), len(splits["test"]))

# Images become float tensors of shape (1, 32, 32).
tensor_ds = ds.with_format("torch")
Downloads are verified with SHA-256 checksums. Set download_dir and
processed_cache_dir to choose local storage locations. Subsequent loads
reuse the processed cache. See the dataset source for its citation.
References
Source: https://archive.ics.uci.edu/dataset/389/devanagari+handwritten+character+dataset
License: Creative Commons Attribution 4.0 International (CC BY 4.0).
Citation: Acharya, S. and Gyawali, P. (2015). Devanagari Handwritten Character Dataset. UCI Machine Learning Repository. https://doi.org/10.24432/C5XS53.